What are the changes? In this post, I will be summarizing the changes to in-memory OLTP component of the product. This feature was first introduced in SQL server 2014. We all know the first release will have limitations. From my past experience with SQL server, new features tend to have limitations. So, what are the improvements?
Schema and data changes: The limitation of altering a table is now removed. You should be able to use alter table on memory-optimized tables to drop, add and alter columns. You should also be able to drop or rebuild indexes.
There is a bit of improvement on parallel plans. Operations that use hash indexes can now be performed in parallel unlike SQL 2014 were the optimizer never creates parallel plan for any operation
SQL 2016 now supports TDE for memory optimized data filegroup.
Support for multiple log reader threads to read transactions that affects memory-optimized tables from transaction log. One more bottleneck removed and this operation is now faster than it was in 2014. SQL server 2016 now allows multiple threads for both recovery and checkpoint, read and apply logged transactions which can result in the ability to scale memory optimized operations.
Some improvements on filestream processing. The removal of dependency on windows files stream processing.
Garbage collection in memory: In SQL 2014 garbage collection was too slow. In some cases, even when memory optimized table was dropped the memory wasn’t immediately available to be used due to slower garbage collection rate as opposed to row version changes. The algorithms of collecting garbage are now improved and hope this is the case.
In SQL 2016, all data whether it from disk or memory optimized tables will be visible immediately on AlwaysOn secondary replica. So less work for developers.
The original recommendation of 250GB of memory for memory-optimized tables are now lifted to 2TB
The requirement for columns of Memory-optimized tables that uses an index to be BIN2 collation is also removed.
Support for more DML operations such as select distinct, different type of joins (such as Left and right outer join), union, union all, nested stored procedure calls, subqueries and OR and not are now added.
Thursday, May 28, 2015


Thursday, May 14, 2015
SQL Server 2016 public preview coming soon
Highlights of the upcoming public preview of SQL server 2016 features:
- Dynamic Data masking
- Row-level Security
- Three synchronous replicas on AlwaysOn
- Native JSON support (Now supporting the world of Big Data)
- More improvements on hybrid backups (pushing more of cloud)
- Built-in advanced analytic, polybase and mobile BI
- Real-time Operational Analytics & In-Memory OLTP
- Stretch database. New technology that allows you to dynamically stretch your warm and cold transnational data to Microsoft Azure
- Always encrypted : as per T.K. Ranga Rengarajan blog "Always Encrypted, based on technology from Microsoft Research, protects data at rest and in motion. With Always Encrypted, SQL Server can perform operations on encrypted data and best of all, the encryption key resides with the application in the customers trusted environment. Encryption and decryption of data happens transparently inside the application which minimizes the changes that have to be made to existing applications"
Tuesday, May 12, 2015
Get SQL Loginame when you know the password
Did you ever found yourself in a situation where a user
knows their sql login password but not username? Well, I did. I want to share this SQL statement that helps
you to retrieve the name of sql login if you know the password.
--will return any name with the same password
as in the Check text.
SELECT name FROM sys.sql_logins
WHERE PWDCOMPARE('' , password_hash) = 1
Tuesday, July 01, 2014
Friday, March 21, 2014
Updatable columnstore clustered indexes, is it new feature for SQL 2014 ?
The new release of SQL server 2014 boosts on improvement of columstore index. As we all know, SQL Server 2012 introduced columnstore indexes. I haven't seen it widely used in data warehouse implementation due to the fact that you can not update. If you want to reload the data you have to drop and re-create the index. This might be possible if you are working with rows less than 1 billion. But if your table is more than 1 billion it is very difficult to use. So, the new release not only made the column store index updatable but also can be clustered index. It is all good news but is this a new feature ? I would say for normal version of SQL server it can be seen as new. But, Microsoft released this feature with SQL Server 2012 Parallel data warehouse. What they did is they moved the technology to new version of SQL server. To claim this is a new technology in my opinion is wrong and misleading. The technology was there in their special version of SQL server 2012 (for Parallel data warehouse).
Wednesday, March 19, 2014
Microsoft's SQL Server 2014 release code: First look
It come so fast after the release of 2012 but the new SQL server has arrived. Read more SQL server 2012 realease
Friday, January 17, 2014
SQL Server 2014 release date?
The exact date of release is still not set but insider from Microsoft thinks it will be released in the first half of 2014. or 3rd Quarter of 2014. Played with CP2 and looks pretty good. Waiting to play with when it is released. As usual, I will wait till SP1 is released before moving any production probably early next year
Wednesday, August 28, 2013
SQL 2014 new feature (Updatable columnstore)
One of the new features introduced on SQL server 2012 was a memory optimized columnstore index. This feature not only reduces the amount of storage but also the speed of the query. During my test, I found that the speed of a query performance before and after columnstore index was in magnitude of 15 times faster. Wow, that was very impressive. As being new feature it have its own drawbacks. You are not able to update the data, hum. The workaround was very cumbersome and not suitable for some of data warehouse solutions. If you want to update data you need to drop the columnstore index update the data and recreate it.
If you have already upgraded to 2012 to make use of the columnstore index then you may have to upgrade to the new SQL server 2014. SQL 2014 doesn’t require the workaround of updating data. The new release enhanced the columnstore to be a pure columnar store. Bang on!!
Data warehouse is much happier place to be with SQL 2014. Not only you will be able to save space but also increase query performance.
Thursday, August 22, 2013
When is SQL server installed
I have been asked may times how to find when a SQL server is installed. Mostly I told them to find the installation log. But, what I didn't realized is that you can find out by querying sys.syslogin database.To my surprise, quiet an easy statement. You can use
SELECT createdate as Sql_Server_Install_Date, *
FROM sys.syslogins
where sid = 0x010100000000000512000000
FROM sys.syslogins
where sid = 0x010100000000000512000000
or
SELECT createdate as Sql_Server_Install_Date
FROM sys.syslogins
where loginname = 'NT AUTHORITY\SYSTEM'
FROM sys.syslogins
where loginname = 'NT AUTHORITY\SYSTEM'
One of the above will do as long as default language is English
Flushing the cache for one database
DECLARE @DBID int
SET @DBID = ( SELECT dbid FROM master.dbo.sysdatabases WHERE name = 'db')
--Flush procedure on the db
DBCC FLUSHPROCINDB (@intDBID)
SET @DBID = ( SELECT dbid FROM master.dbo.sysdatabases WHERE name = 'db')
--Flush procedure on the db
DBCC FLUSHPROCINDB (@intDBID)
Friday, May 17, 2013
Execution plan puzzle
I recently come accross a query that used to run fine on production server but suddenly
Execution plans can be affected by different statistics, parallelism due to number of processors, the amount of available RAM in the server, different service packs, different server configuration settings, and the current load on the server. I imagine one or more of these are causing what you are seeing.
Friday, May 11, 2012
SQL server system table corruption
Recently I came across a sage database that has been corrupted. When running DBCC CHECKDB command I was getting the following errors:
There are 226 rows in 1 pages
for object "sys.sysprivs".
DBCC results for
'sys.sysschobjs'.
Msg 2511, Level 16, State 1,
Line 1
Table error: Object ID 34,
index ID 2, partition ID 562949955649536, alloc unit ID 562949955649536 (type
In-row data). Keys out of order on page (1:47), slots 66 and 67.
Msg 2511, Level 16, State 1,
Line 1
Table error: Object ID 34,
index ID 2, partition ID 562949955649536, alloc unit ID 562949955649536 (type
In-row data). Keys out of order on page (1:47), slots 72 and 73.
Msg 2511, Level 16, State 1,
Line 1
Table error: Object ID 34,
index ID 2, partition ID 562949955649536, alloc unit ID 562949955649536 (type
In-row data). Keys out of order on page (1:47), slots 93 and 94.
There are 4147 rows in 93
pages for object "sys.sysschobjs".
CHECKDB found 0 allocation
errors and 3 consistency errors in table 'sys.sysschobjs' (object ID 34).
Normally the re-indexing should have fixed this type of issue when the base table is user table but it didn't. To fix the issue I have to perform the following commands
use DatabaseName
go
ALTER DATABASE DatabaseName
SET SINGLE_USER
go
DBCC CHECKDB('DatabaseName', REPAIR_REBUILD)
go
The outcome from the above command was
Repair: The Nonclustered
index successfully rebuilt for the object "sys.sysschobjs, nc1" in
database "FCE_Sage".
Msg 8945, Level 16, State 1,
Line 1
Table error: Object ID 34,
index ID 2 will be rebuilt.
The error has been repaired.
Msg 2511, Level 16, State 1,
Line 1
Table error: Object ID 34,
index ID 2, partition ID 562949955649536, alloc unit ID 562949955649536 (type
In-row data). Keys out of order on page (1:47), slots 66 and 67.
The error has been repaired.
Msg 2511, Level 16, State 1,
Line 1
Table error: Object ID 34,
index ID 2, partition ID 562949955649536, alloc unit ID 562949955649536 (type
In-row data). Keys out of order on page (1:47), slots 72 and 73.
The error has been repaired.
Msg 2511, Level 16, State 1,
Line 1
Table error: Object ID 34,
index ID 2, partition ID 562949955649536, alloc unit ID 562949955649536 (type
In-row data). Keys out of order on page (1:47), slots 93 and 94.
The error has been repaired..
Tuesday, April 24, 2012
Latest version of SQL server
To get an idea of what the latest version of SQL server will be, you can ask a SQL guru @Ask SQL Guru
Cannot shrink tempdb
How to shrink tempDB
SELECT * FROM sys.dm_exec_requests WHERE database_id = 2
select * from sys.dm_tran_locks
where resource_database_id= 2
select * from sys.dm_db_session_space_usage
where user_objects_alloc_page_count<> 0
SELECT * FROM sys.all_objects
where is_ms_shipped = 0
DBCC FREEPROCCACHE
BCC SHRINKFILE ('tempdev', 1024)
Purge all data in database
Recently I have been tasked to purge all data in the database. When trying to delete data from tables which have foreign key relationship the standard purge routine will fail or you have to spend time to get which table to purge first. Also there is an issue of identity as when you delete data from the table the identity will not go back to starting point. After few research, I have got the best method which is shown below.
1. Disable all constraints in the database using the following command
exec sp_msforeachtable "ALTER TABLE ? nocheck contraint all"
2. Delete all data in the database
exec sp_MSForEachTable "DELETE FROM ?"
3. Enable all constraints
exec sp_msforeachtable "ALTER TABLE ? WITH CHECK CHECK CONSTRAINT all"
4. Reset tables with identity. Note when you run the following it will give you error if the table doesn't have identity column. Ignore the errors.
exec sp_MSforeachtable "DBCC CHECKIDENT ( '?', RESEED, 0)"
Friday, January 27, 2012
SQL server 2012 lauch date
New version of SQL server 2012 launch date is set for 7th of March. The offering will be in three main edition. Details of edition feature comparison can be found at Feature comparison
Enterprise Edition (EE) will be licensed based on compute capacity measured in cores
Business Intelligence (BI) Edition will be available in the Server + CAL model, based on users or devices
Standard Edition (SE) offers both licensing models to address basic database workloads
There will be Web Developer and Express versions but this is not detailed enough and we just have to wait and see.
SQL Server 2012 will continue to offer two licensing options one is based on
one based on computing power and the other is based on based on users or devices. The way the power is measured is not processor rather core based.
Friday, October 14, 2011
Partitioning an existing table and archiving part I
Recently, I have been tasked to come up with a solution to partition a table with clustered index. Previously, I have setup partition from scratch and was loading data to the new partition from non-partitioned table. When a table that you want partition have got a clustered index the job is much easier. I have followed the following steps to achieve my goal.
You don't need to do step 1 to 4 when the database and table/data exists. This is for demo and completeness purposes. You can directly jump to step 5
1.Create database
2. Create table
3. Populate sample data
4. Create Index on existing table
The idea is to move all the data that is created before 2009 as archive and the others as one year partition. Effectively
< 1 Jan 2009
Jan 1 2009 to 31 Dec 2009
Jan 1 2010 to 31 Dec 2010
>= Jan 1 2011
Which means we will have four partitions.
5. Create Filegroups and add file to each Filegroup. For demo purpose I added only one file per Filegroup. As you can see below I created four Filegroups. One Filegroup for each partition. But, you don't have to create four Filegroups. You can use only one Filegroup for all partition but it is better for maintenance purposes and if you want move one Filegroup to different spindle it make it much easier.
6. Create partition function and scheme
7. See current status of our table. Up to now our table is in a default partition. See figure below.
8. Move table to partition based on LastUpdated column of the table.
To perform this, I need to drop the index and recreate it on partition scheme that I have created above.
Just by creating my clustered index on partition scheme moved all the data in their respective partition. see result set below.
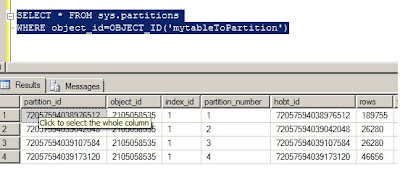
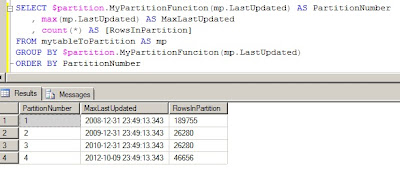
Let us now see where the our data has gone. The following query will show us the Maximum lastupdated value in particular partition, partition number and total number of rows in each partition. See the output result below.
In part II, I will show how easy it is to move archived data and able to delete without affecting performance of your system.
You don't need to do step 1 to 4 when the database and table/data exists. This is for demo and completeness purposes. You can directly jump to step 5
1.Create database
CREATE DATABASE MyPartitionDB
2. Create table
CREATE TABLE mytableToPartition(MyId INT IDENTITY(1,1), LastUpdated datetime)
3. Populate sample data
declare @timedate datetime
set @timedate = DATEADD(YEAR, -10, GETDATE())
while @timedate < '20121010'
begin
INSERT INTO mytableToPartition (LastUpdated)
values (@timedate)
set @timedate = DATEADD(MINUTE, 20, @timedate)
end
4. Create Index on existing table
CREATE clustered index CL_MyId on mytableToPartition(MyId)
The idea is to move all the data that is created before 2009 as archive and the others as one year partition. Effectively
< 1 Jan 2009
Jan 1 2009 to 31 Dec 2009
Jan 1 2010 to 31 Dec 2010
>= Jan 1 2011
Which means we will have four partitions.
5. Create Filegroups and add file to each Filegroup. For demo purpose I added only one file per Filegroup. As you can see below I created four Filegroups. One Filegroup for each partition. But, you don't have to create four Filegroups. You can use only one Filegroup for all partition but it is better for maintenance purposes and if you want move one Filegroup to different spindle it make it much easier.
ALTER DATABASE MyPartitionDB ADD FILEGROUP FG1;
ALTER DATABASE MyPartitionDB ADD FILEGROUP FG2;
ALTER DATABASE MyPartitionDB ADD FILEGROUP FG3;
ALTER DATABASE MyPartitionDB ADD FILEGROUP FG4;
-- now add file to each filegroup
ALTER DATABASE MyPartitionDBADD FILE(name='FG1',FILENAME='C:\temp\fg1.ndf') TO FILEGROUP FG1
ALTER DATABASE MyPartitionDB ADD FILE(name='FG2',FILENAME='C:\temp\fg2.ndf') TO FILEGROUP FG2
ALTER DATABASE MyPartitionDB ADD FILE(name='FG3',FILENAME='C:\temp\fg3.ndf') TO FILEGROUP FG3
ALTER DATABASE MyPartitionDB ADD FILE(name='FG4',FILENAME='C:\temp\fg4.ndf') TO FILEGROUP FG4
6. Create partition function and scheme
GO
-- create partition function
CREATE PARTITION FUNCTION MyPartitionFunciton (datetime)
AS RANGE RIGHT FOR VALUES ('20090101', '20100101', '20110101');
GO
-- create partition scheme
CREATE PARTITION SCHEME MypartitionScheme
AS PARTITION MyPartitionFunciton TO (FG1,FG2,FG3,FG4)
GO
7. See current status of our table. Up to now our table is in a default partition. See figure below.

8. Move table to partition based on LastUpdated column of the table.
To perform this, I need to drop the index and recreate it on partition scheme that I have created above.
-- drop existing index
DROP INDEX mytableToPartition.CL_MYID
-- re-create index on the partitionscheme
go
CREATE CLUSTERED INDEX CL_MYID on mytableToPartition(myid) on MypartitionScheme(run_date)
Just by creating my clustered index on partition scheme moved all the data in their respective partition. see result set below.

Let us now see where the our data has gone. The following query will show us the Maximum lastupdated value in particular partition, partition number and total number of rows in each partition. See the output result below.

In part II, I will show how easy it is to move archived data and able to delete without affecting performance of your system.
Monday, October 10, 2011
Why going back to ODBC?
Yes, that is my question. For the last few years Microsoft was pushing for OLE DB connectivity. Now, microsoft is going to phase out support for OLE DB. The main reason that have been given is portability. Well, why moved from ODBC in the first place. It is also mentioned on the article that the last OLE DB supported database is the next release of SQL Server (Denali). Microsoft have given a timeline when everybody should port thier application to ODBC 7 years. I am not sure why this move is a must. If it does work, why break and create hasle for the microsoft community who have adopted OLE DB?
Thursday, October 06, 2011
Transfer sql server logins between different versions
A very good kb from Microsoft that helps to transfer login between earlier version of SQL Server (7.0 and 2000) to new version. The script and full implication can be found @ Transfer SQL Server logins
Tuesday, August 09, 2011
SQL Server Trace flags
A very comprehensive list of SQL Server trace flags have been put together by Yusuf Anis on SQL Server Trace flag. A good starting point and reference for trace flag,
Subscribe to:
Posts (Atom)